Products / AI Developer Tools
EvalHarness
LLM eval suite starter: JSONL, offline matchers, CLI + HTML report
JSONL eval datasets with exact/contains/regex matchers, optional LLM-as-judge (BYOK), CLI pass rates, and a self-contained HTML report.
Value
Problem. Prompt and agent changes ship without regression gates. Hosted eval platforms add lock-in for simple string/regex checks.
How it helps. JSONL eval datasets with exact/contains/regex matchers, optional LLM-as-judge (BYOK), CLI pass rates, and a self-contained HTML report.
Why buy. CI-friendly offline matchers plus optional judge — fork it, no cloud dashboard required.
- JSONL datasets + optional predictions merge
- exact / contains / regex / llm_judge runners
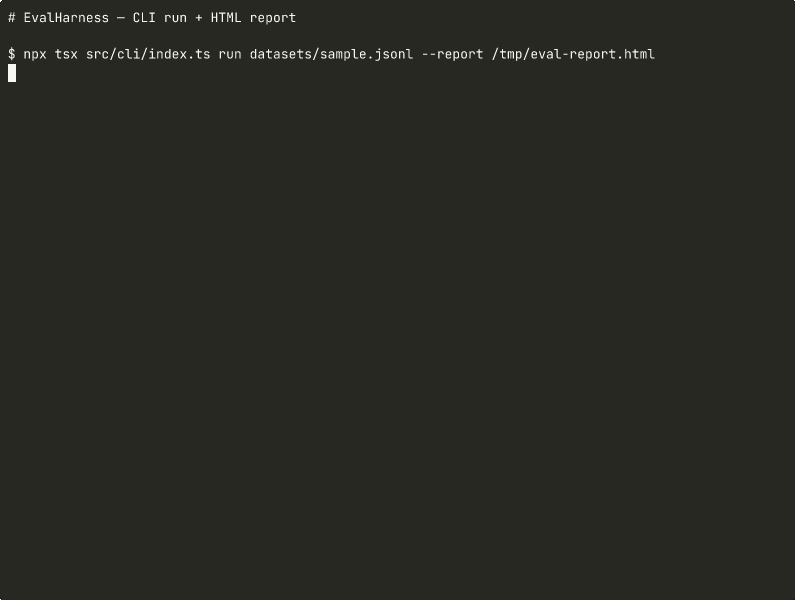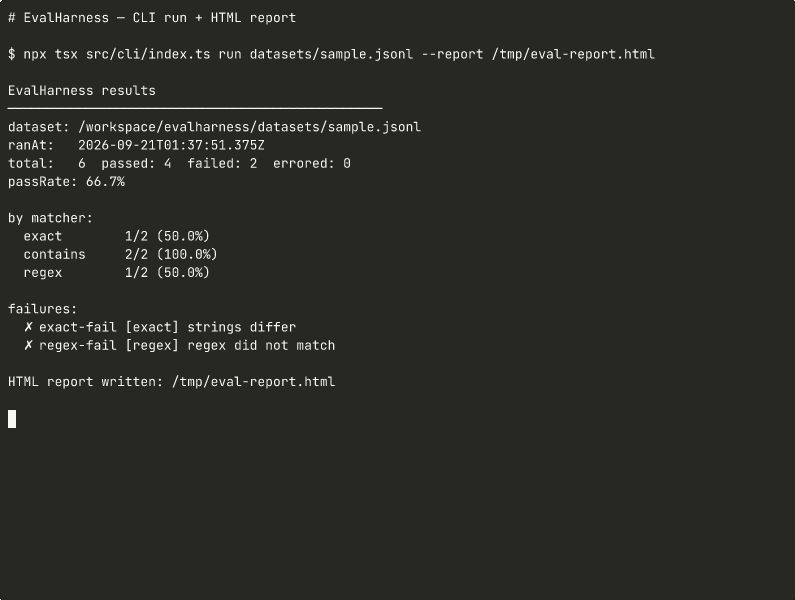
- CLI pass rates, --fail-under, HTML report
How it works
flowchart LR
  DS["dataset.jsonl"] --> Load["loadDataset"]
  Pred["predictions.jsonl"] --> Merge["mergePredictions"]
  Load --> Merge
  Merge --> Run["runSuite"]
  Run --> CLI["CLI pass rates"]
  Run --> HTML["HTML report"]
Mermaid flowchart (render in GitHub / VS Code / mermaid.live).
Use case
Run datasets/sample.jsonl in CI; fail the job when passRate drops below --fail-under.
What you get
- Library + CLI
- datasets/sample.jsonl + examples
- Console + HTML reporters
- 18 Vitest tests
- MIT license
Project structure
evalharness/
  src/
    dataset.ts, suite.ts, types.ts
    runners/  report/  cli/
  datasets/ examples/ tests/
Quick start
npm install && npm test && npm run build
npx tsx src/cli/index.ts run datasets/sample.jsonl --report report.html
Example
From datasets/sample.jsonl
{"id":"exact-ok","expected":"4","output":"4","matcher":"exact"}
{"id":"contains-ok","expected":"billing","output":"Label: billing","matcher":"contains","ignoreCase":true}
{"id":"regex-ok","expected":"^ORD-\\d{4}$","output":"ORD-2048","matcher":"regex"}
Tested
18 Vitest tests — dataset load, runners, suite aggregation, HTML report, CLI including --fail-under.
npm test2026-09-20 — 18 passed; npm run build OK
Design decisions
- Offline matchers need no API key — preferred CI gate
- Exit code 1 on failures for pipelines
- Dark self-contained HTML report for sharing without a server
Limitations
- Not a hosted eval platform with dashboards
- llm_judge quality depends on your model/rubric
- No built-in dataset versioning UI
- You supply model outputs (inline or --predictions)
Who it’s for
Teams gating prompt/agent changes in CI with honest pass rates.
Not for: Orgs that need a managed eval SaaS with crowd labeling.
What you own
Full MIT-licensed TypeScript source via Gumroad ZIP. Fork it, ship it commercially, keep the license notice. You are responsible for secrets, hardening, and production ops.
Related
PromptKit · AgentForge · RagPipe · McpForge
Demo